


Two years ago I wrote an essay about AI-assisted coding, and one of my tips was to review every line of generated code. I’d give that advice very differently today.
What I’d say now is this: you don’t need to read all the code. Every change still needs some review and every change still needs a person who owns the decision to ship it. What’s changed is that a careful human read of every line is no longer the only way to provide that review, or always the best one. Some can be primarily agent-reviewed or a mix of human/agent when sensitive.
This post is about what I think should take its place, and what happens when nothing does.
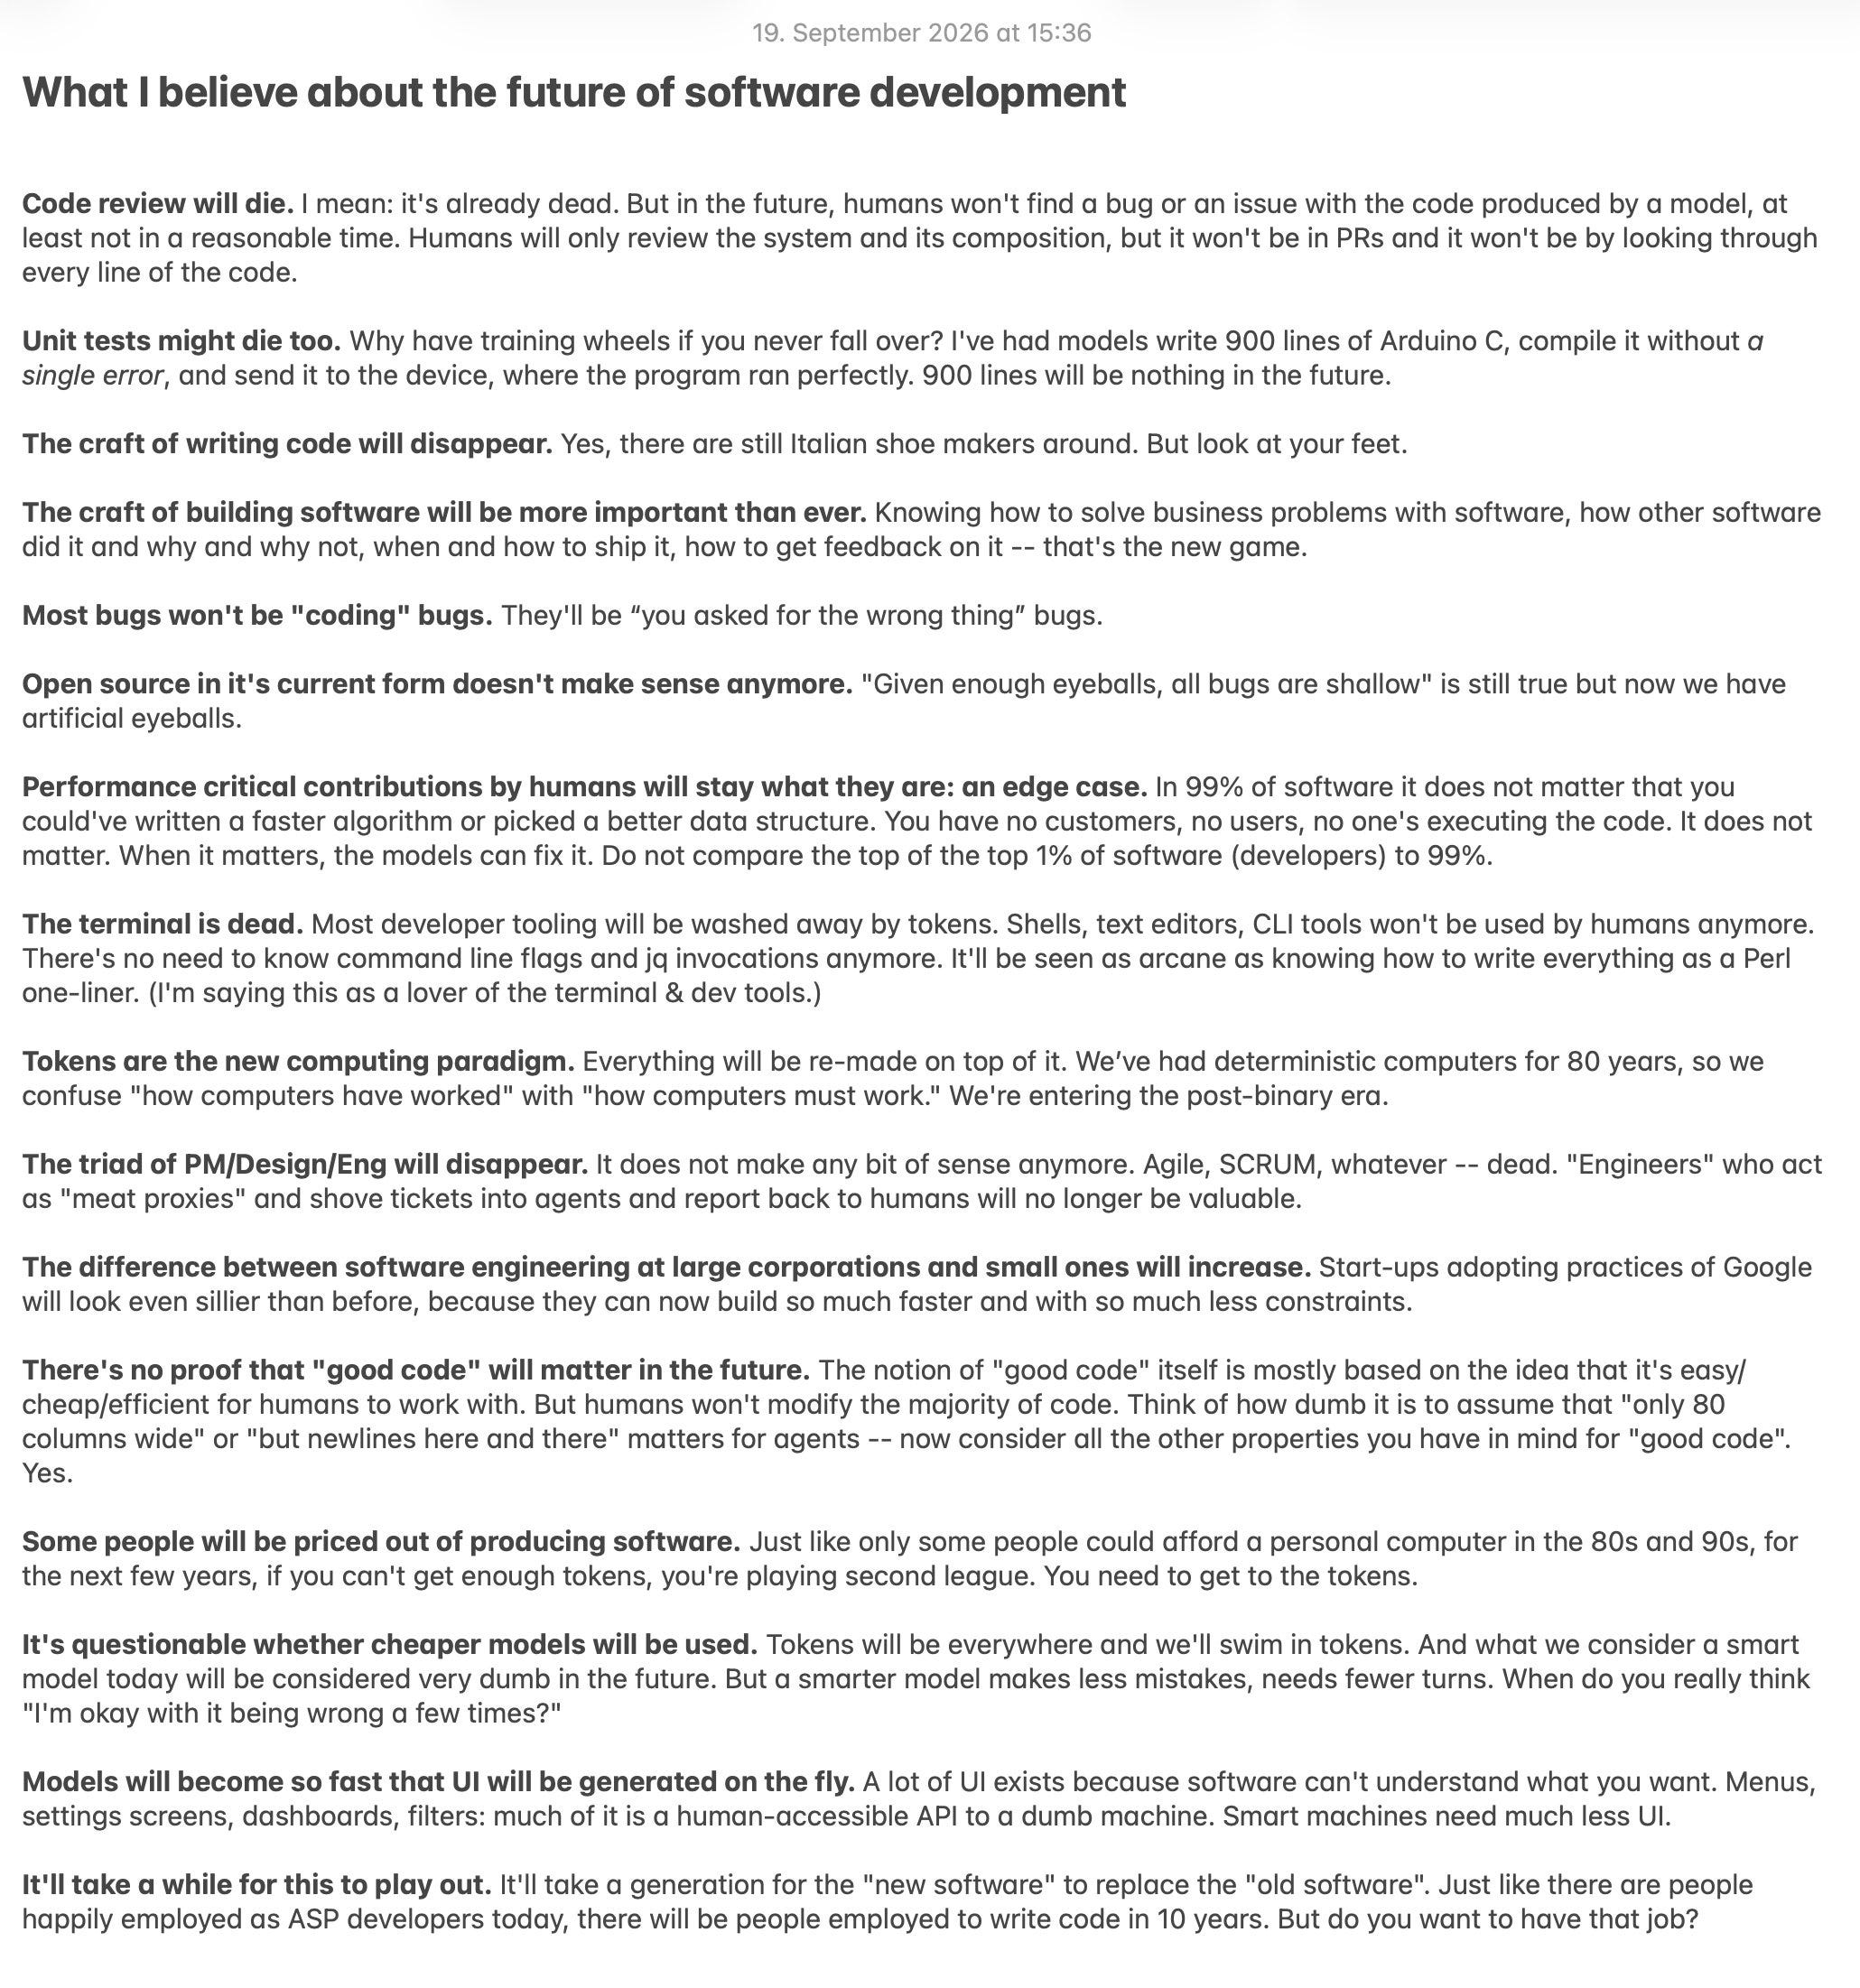
Last week Thorsten Ball posted a list of sixteen things he believes about the future of software development. The first one is “code review will die.” I agree with much of the list, at least on direction, though I’d put that first one differently. Line-by-line reading is going away for a lot of code. Review, meaning someone deciding what ships and being answerable for it, isn’t. What a list like his can’t tell you is how fast each item arrives, or in which parts of the industry. That’s where I actually disagree with people.
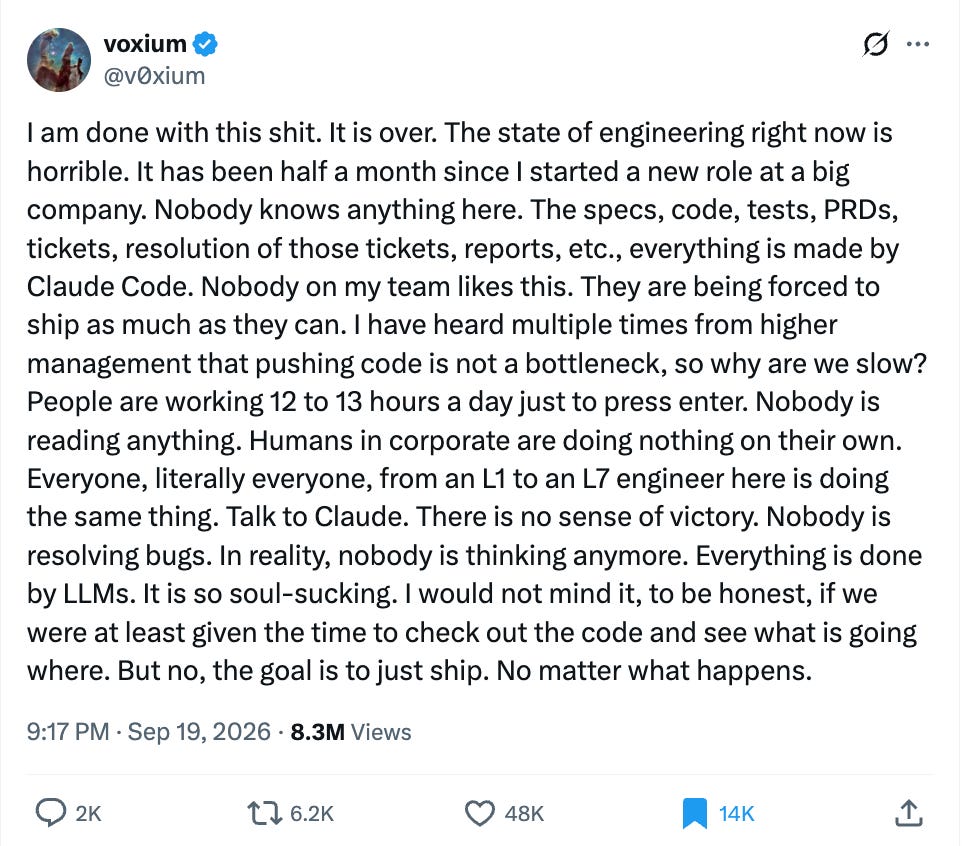
The same week, a very different post ^ went just as far. An engineer two weeks into a new job at a big company wrote about spending their days pressing enter on code nobody reads. More than eight million people saw it. I don’t think these two posts contradict each other. One describes the destination. The other describes what happens when a company drives there without building the road.
Here’s my view in short. I think every industry will stop reading most of its code line by line once it has some other good reason to trust that code.
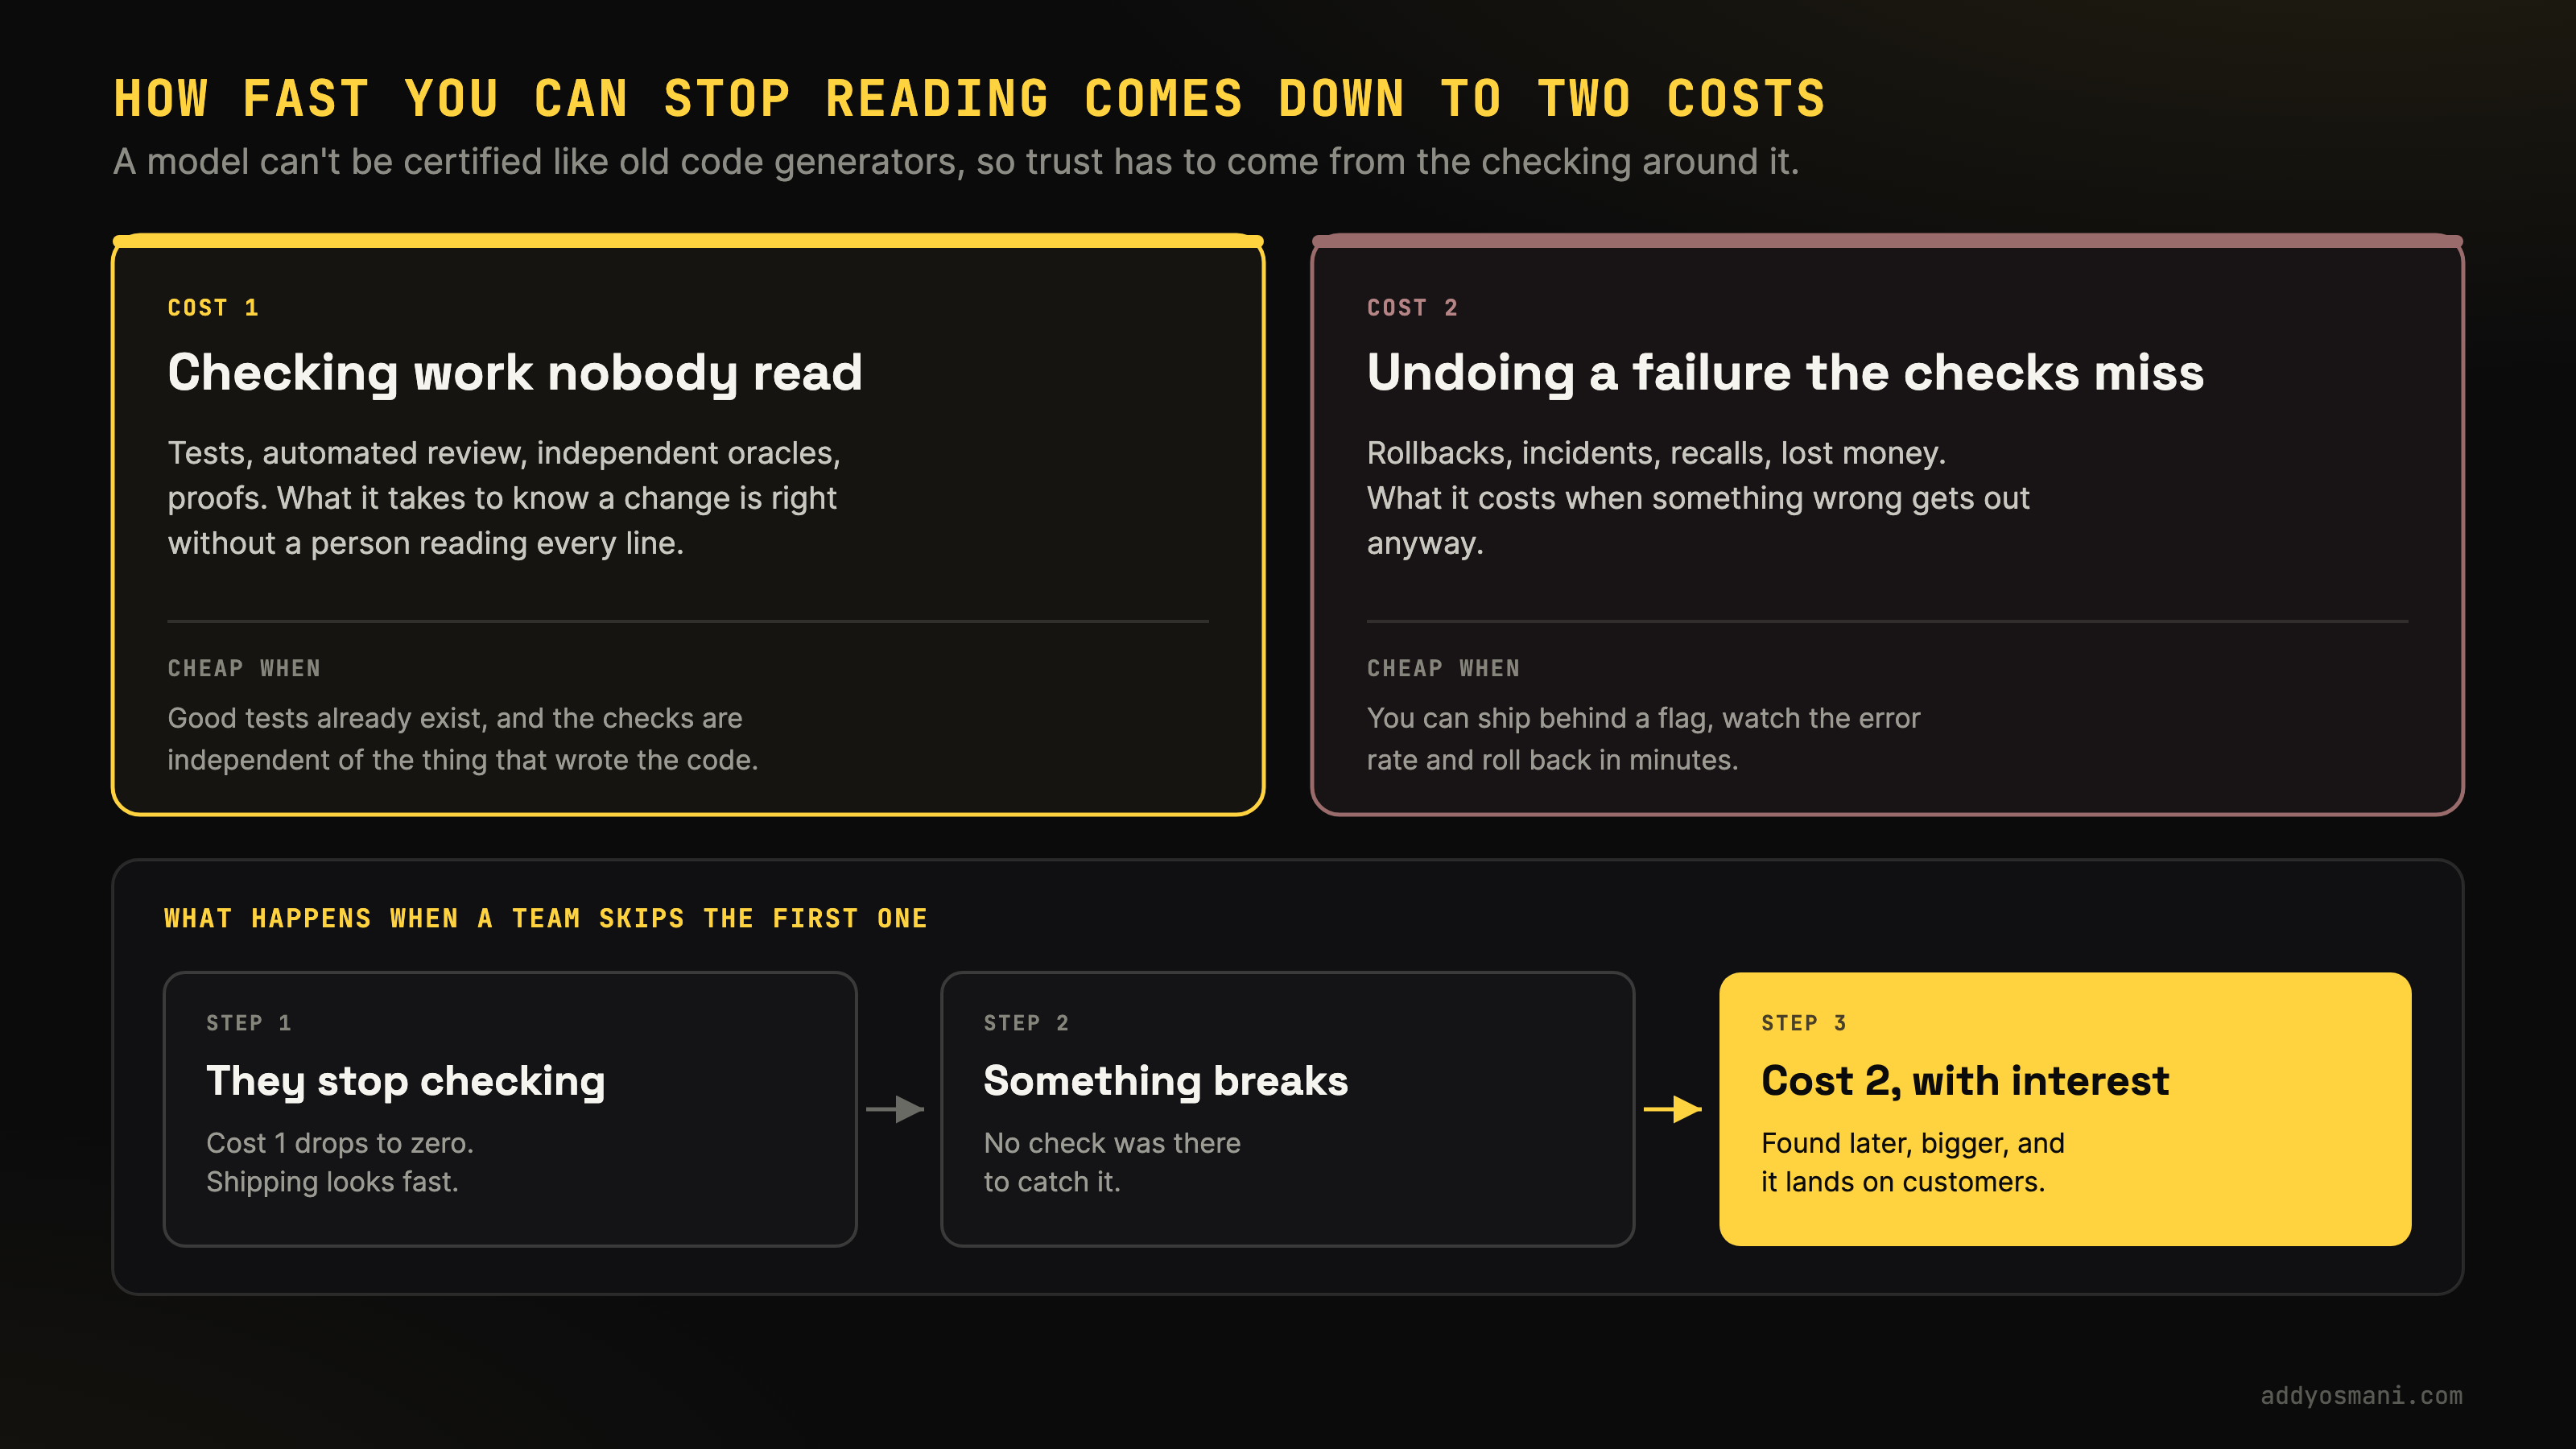
What’s different this time is that the thing writing the code can’t be certified the way older code generators were, because it doesn’t reliably give the same answer twice. So the trust has to come from the checking we build around it. How fast a team or an industry gets there depends on two costs: the cost of checking work nobody read, and the cost of undoing a failure the checks miss.
I should say up front that I’m not neutral. I help build a tool that writes code. When people called Thorsten a shovel seller telling everyone to dig, he said the causality runs the other way: he builds agents because he believes in them. That’s true for me too.
Do I miss anything about the old way? Honestly, yes. At the very start of one of my JavaScript books, I wrote that good code is like a love letter to the next developer who has to maintain it. I meant it. That was before AI, when a lot of us cared about the craft of the code itself. I liked Thorsten’s line that there are still Italian shoemakers around, but look at your feet. Things change. What I get in exchange is the ability to reshape the clay very quickly, and to build things I would otherwise have kicked around for years without ever starting.
What review was actually for
In 2013, Microsoft researchers studied code review and asked developers why they did it. Finding defects was the top answer. The comments told a different story. Of the 570 review comments the researchers classified, only 14% were about defects. The rest were about teaching, sharing context, suggesting better approaches and keeping team norms. Review was never mostly about bugs, which is why “the machines will review it” is a weaker answer than it sounds.
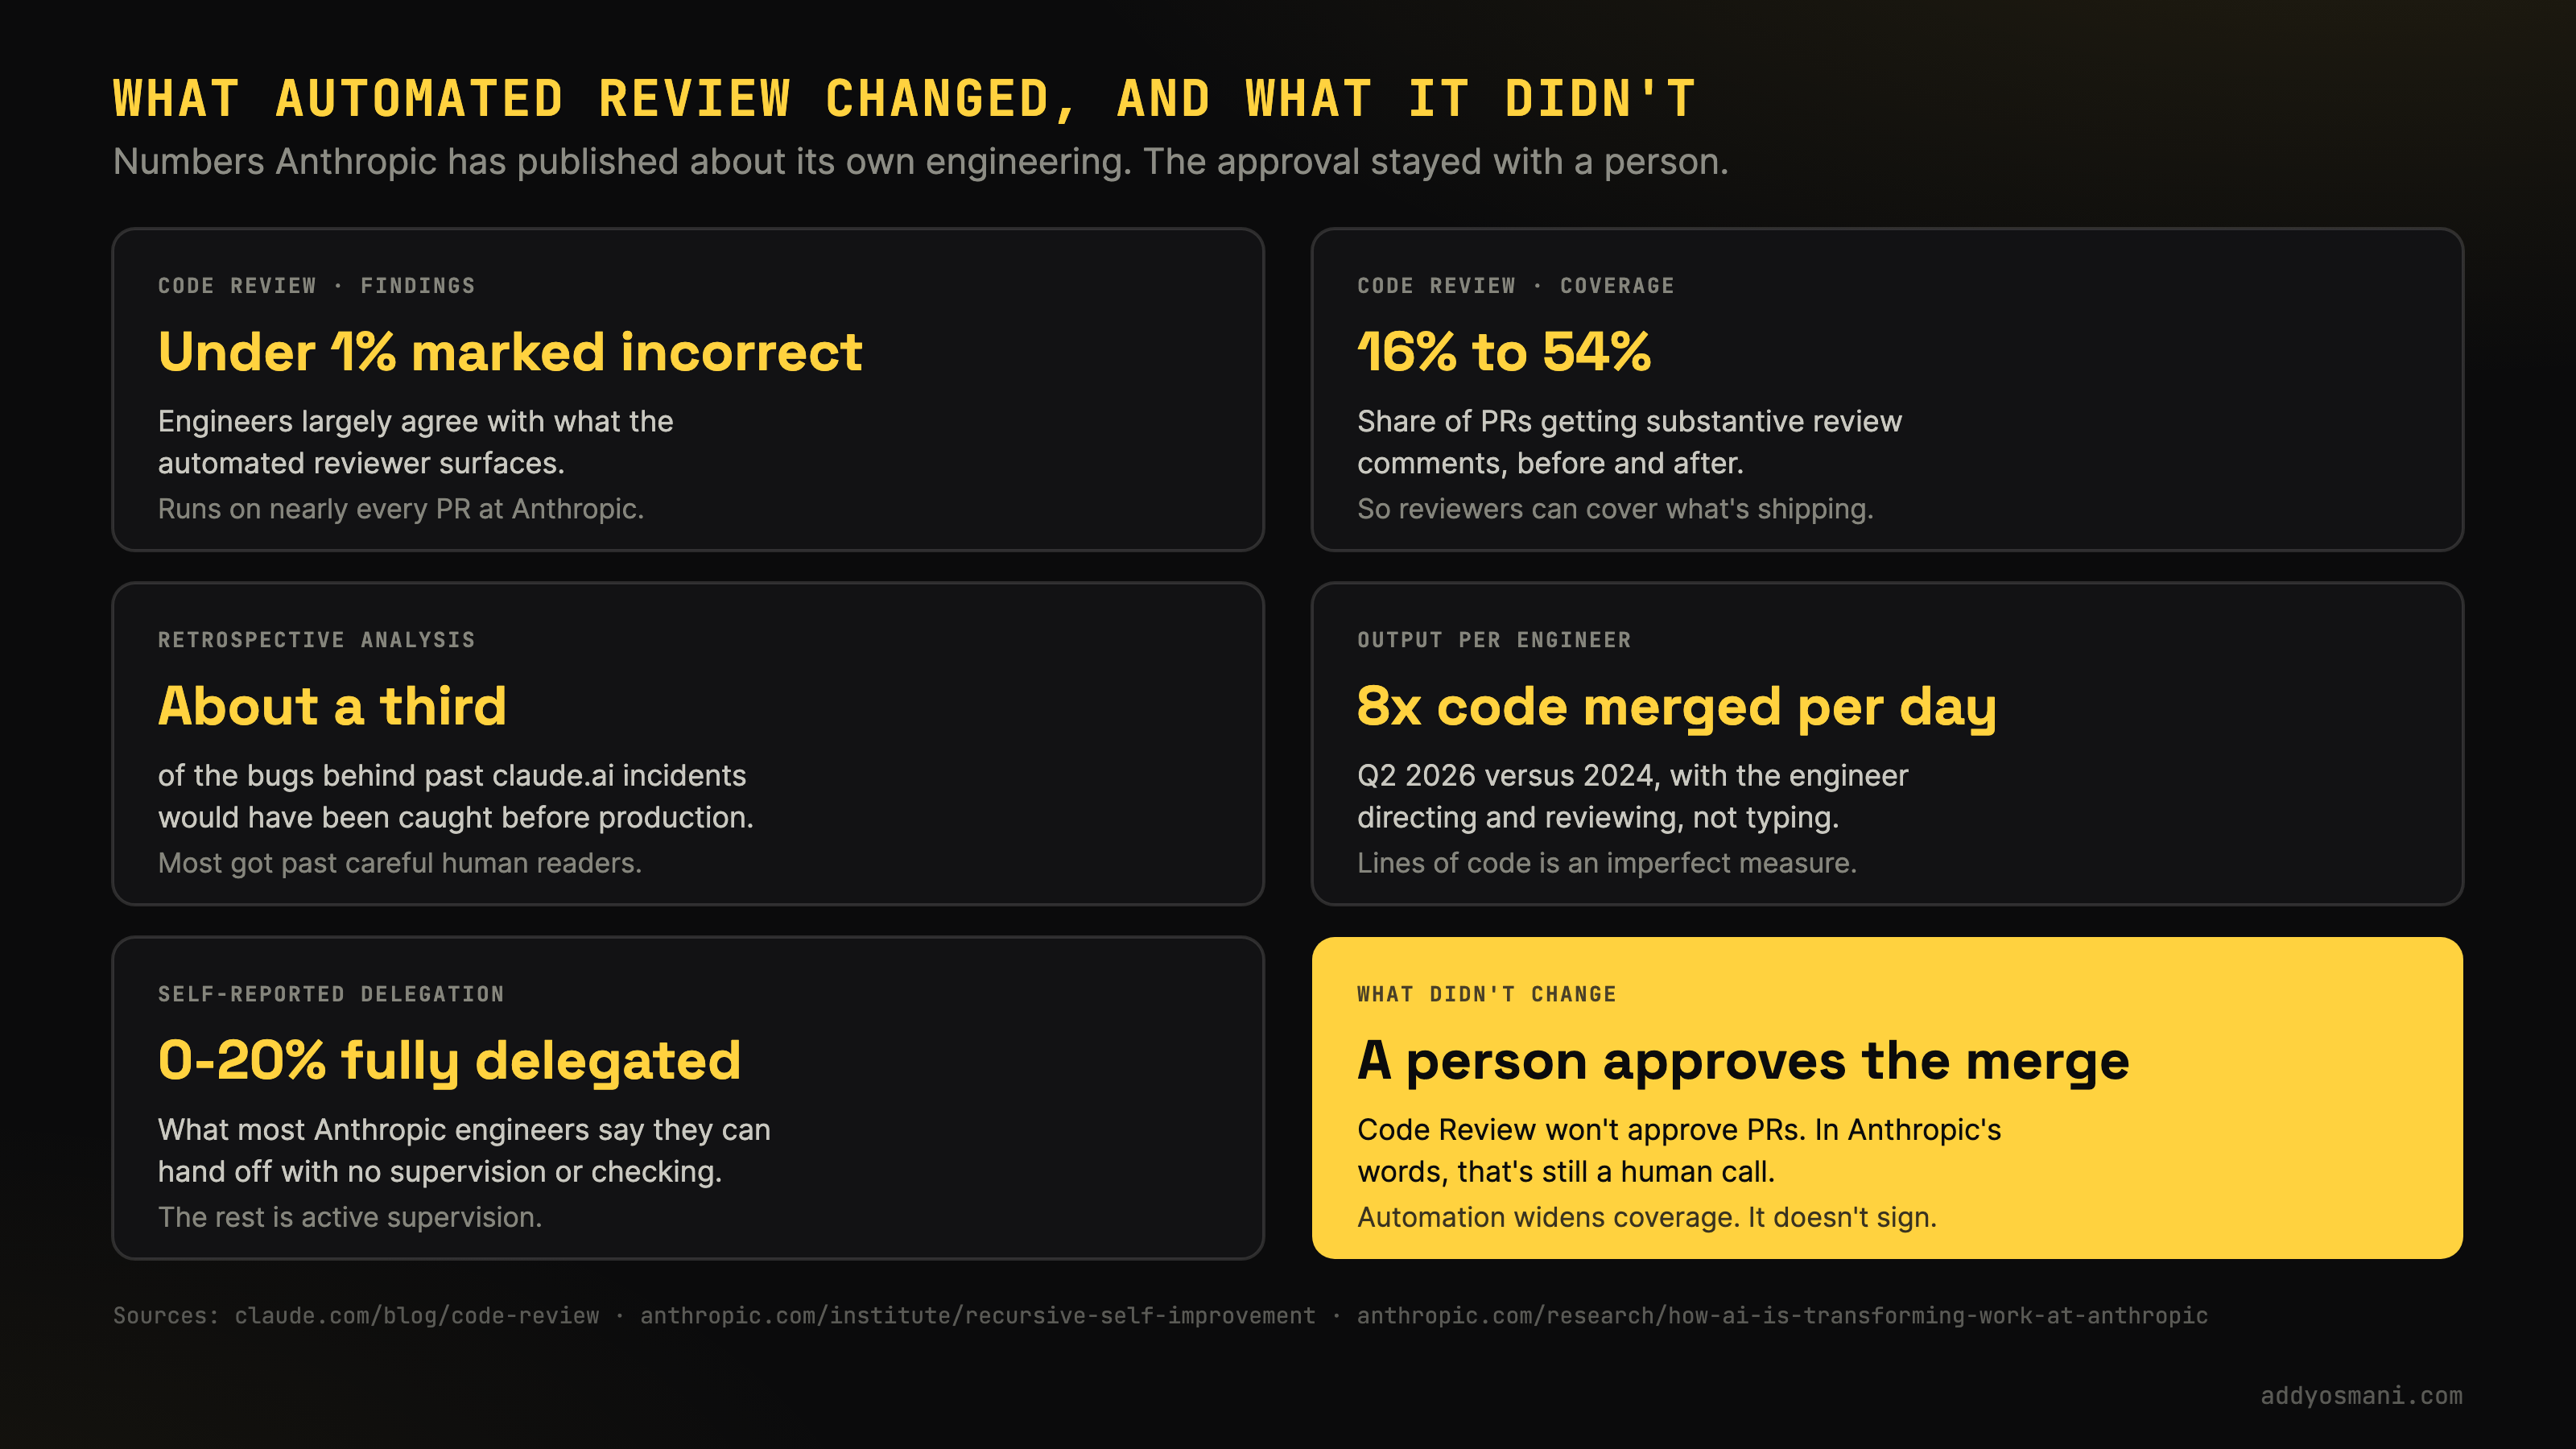
Bug-catching is the part machines are getting good at. At Anthropic, an automated Claude reviewer runs on nearly every PR, and engineers mark less than 1% of its findings as incorrect. Since it started, the share of PRs getting substantive review comments has gone from 16% to 54%. It doesn’t approve anything. In Anthropic’s words, “that’s still a human call.” In a retrospective analysis, Anthropic found that an automated review of every change would have caught roughly a third of the bugs behind past incidents on claude.ai before they reached production.
For a reviewer that never gets tired, a third is a lot. But it also tells you something uncomfortable: most of those bugs got past careful people looking right at the change. My guess is that’s because code that fails in production often looks fine in the diff.
In the second quarter of 2026, the typical Anthropic engineer was merging about eight times as much code per day as in 2024, with the engineer, as Anthropic puts it, “directing and reviewing, rather than typing.” Nobody reads eight times as much code carefully. From the inside, the way we work feels very different from what I was used to. We generate a lot of code every day across a lot of product surfaces, and not every line gets a careful human read anymore. Nearly every change gets automated review, a person still approves what merges, and it’s up to that person to decide how deep to go. Does this change need a careful manual review? Is the tooling we have good enough here? Is this a sensitive enough part of the system that it needs extra scrutiny? If the code passes its tests, performs well on them and runs in production without problems, that’s a pretty good signal.
It’s worth being clear about the limits of that, too. When Anthropic surveyed its own engineers, most said they could “fully delegate” only 0-20% of their work to Claude. The rest still involves active supervision and checking, especially on high-stakes work. Not reading every line isn’t the same as not paying attention.
What worries me more are the other jobs review used to do. It was how junior engineers learned how senior engineers think. Anything a reviewer used to say in a comment, like “we don’t do it that way here” now needs to be written down in skills. Otherwise the agent never hears it.
When the reading stops and nothing replaces it
The problem isn’t that nobody reads the code. It’s that nothing replaced the reading. That team earlier on didn’t move trust from the diff to the checks. It stopped reading diffs and put velocity where trust used to be. They did the transition in the worst possible order, and my two costs predict how it ends. They’ve made the first cost zero by not checking at all, so they’ll pay the second one, undoing the failures no check was ever there to catch, with interest.
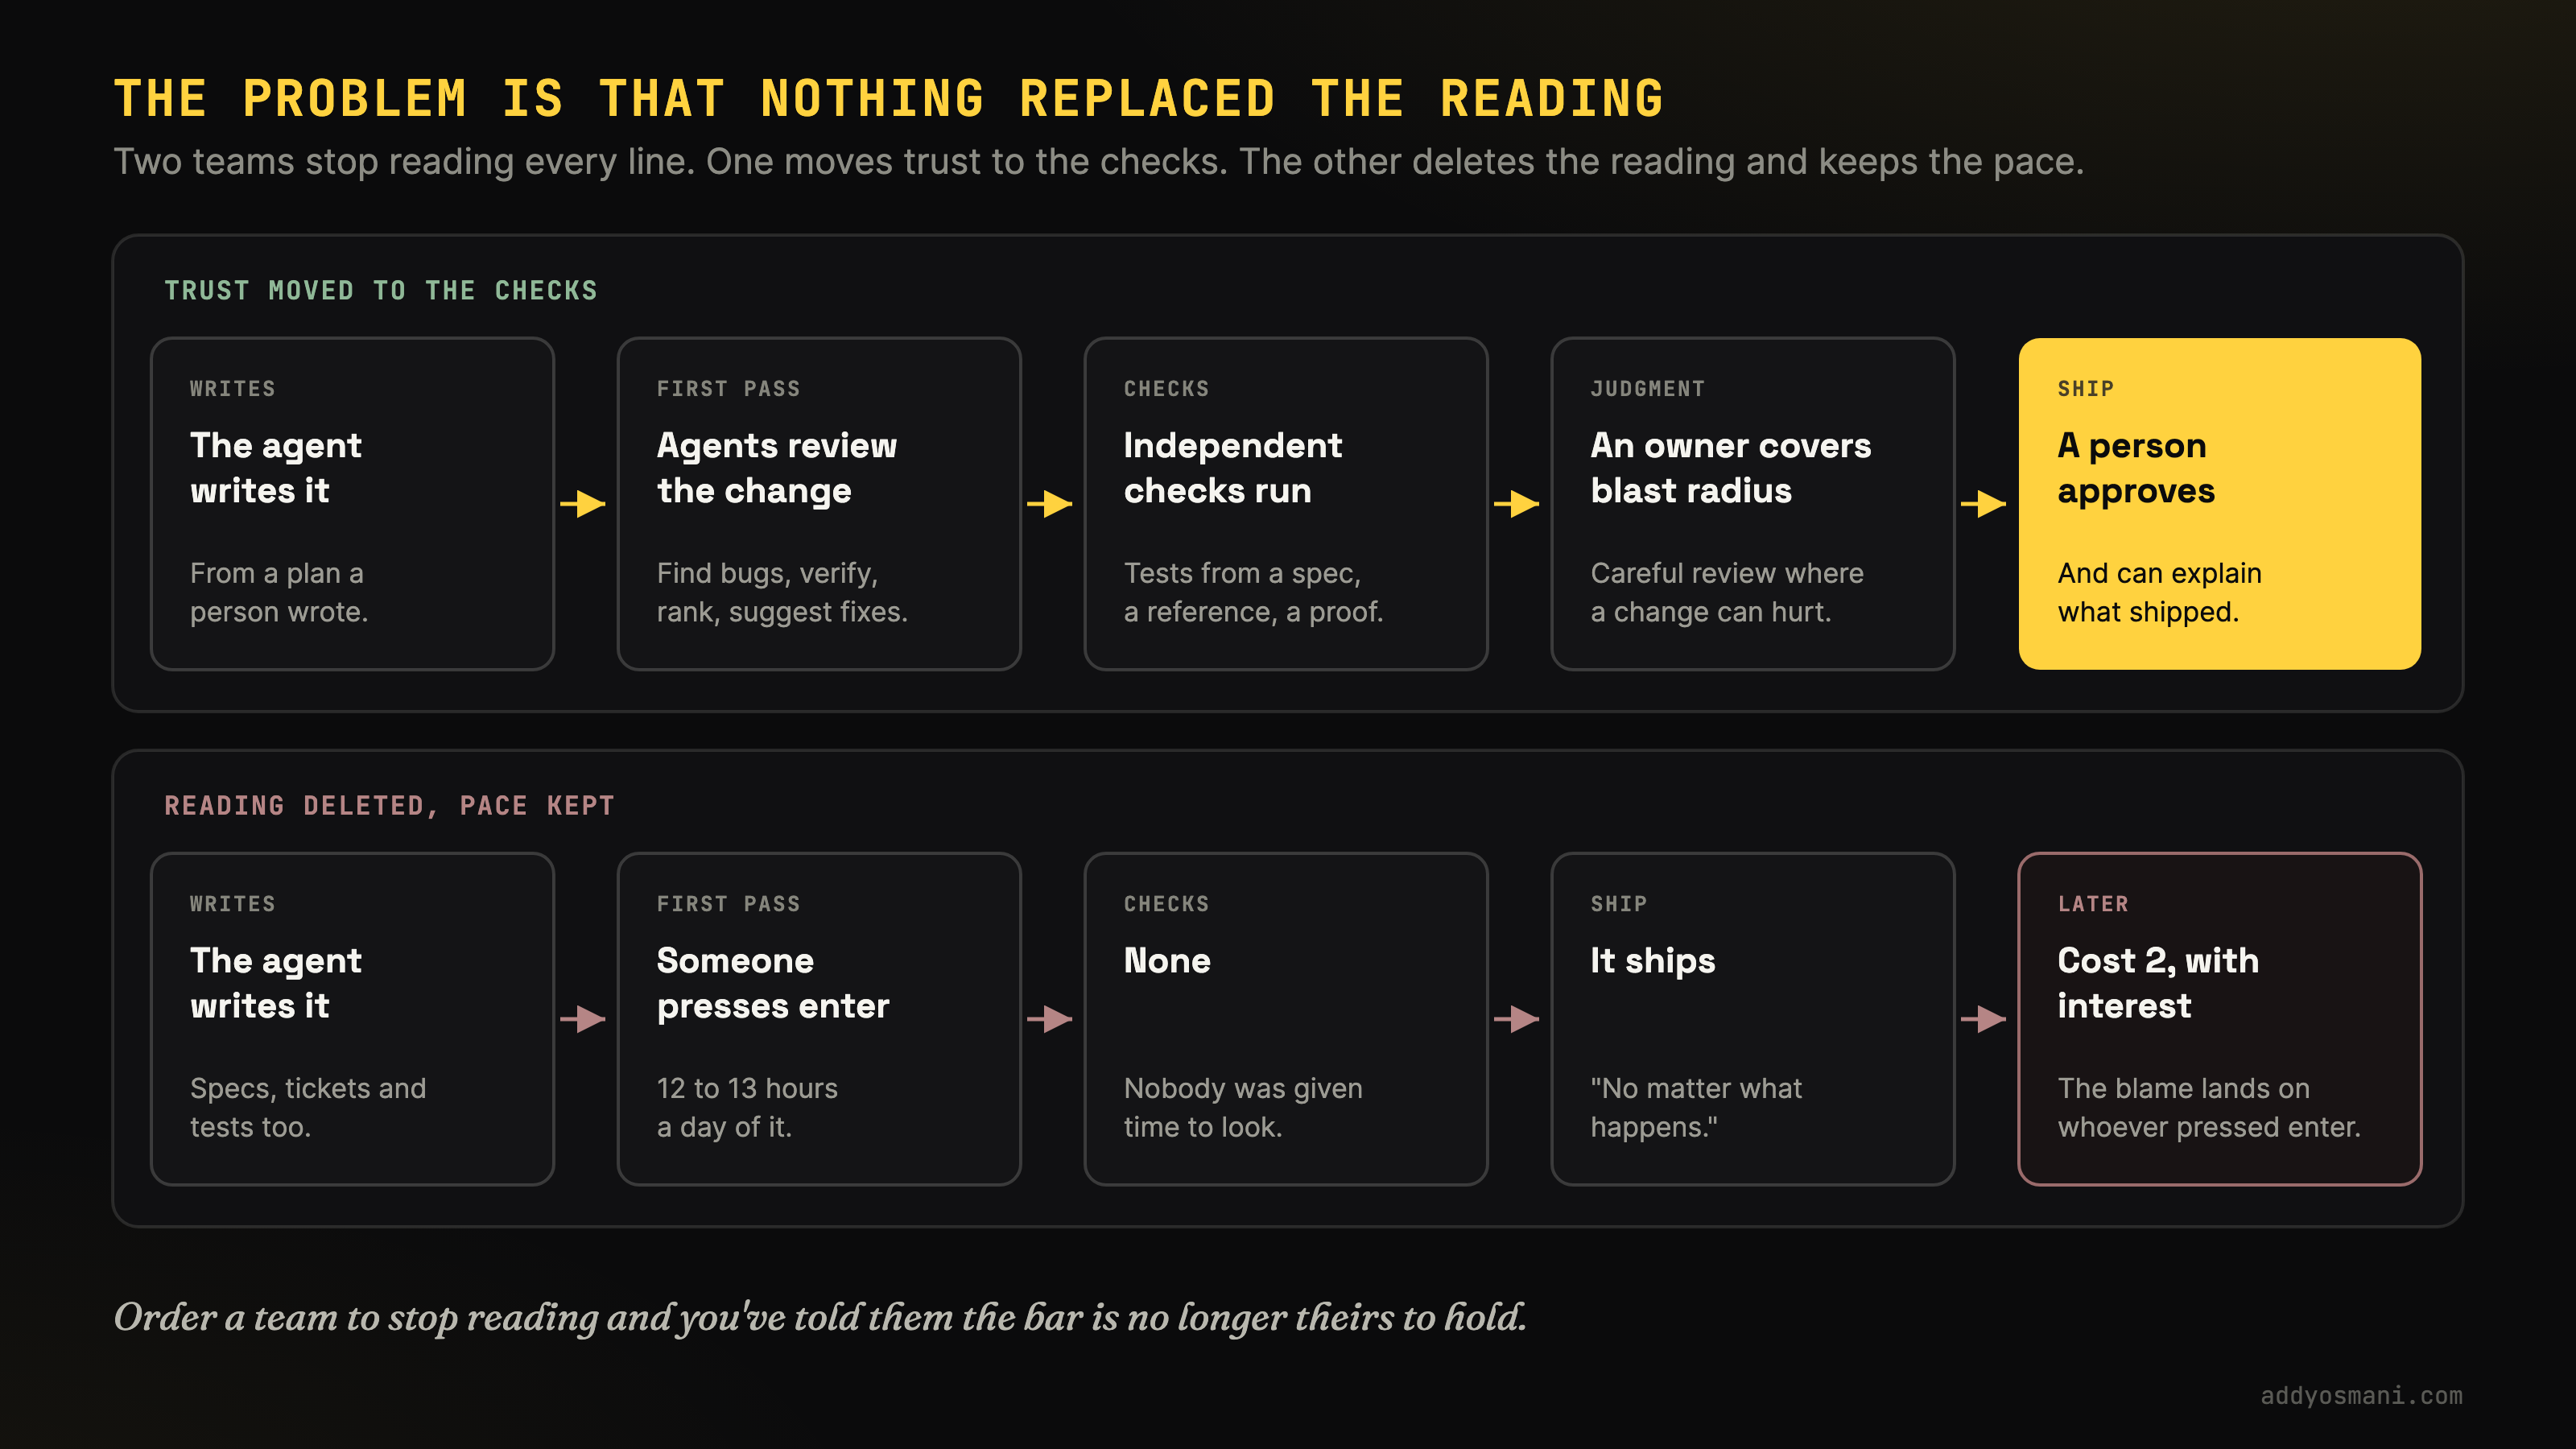
That order wasn’t an accident either. Someone above the people living with it made a decision: once writing code stopped being the bottleneck, the only question left was why anything was still slow. These tools usually spread bottom-up, with individual developers deciding they help. This way of working was imposed top-down, and that difference matters a lot. Think back to what review was doing: teaching, keeping people aware of changes, letting a team hold its own quality bar. Order a team to stop reading and you haven’t just removed a defect check. You’ve told them the bar is no longer theirs to hold.
The version that works is boring by comparison. Every PR gets a multi-agent first pass that finds bugs, verifies them, ranks them by severity and suggests fixes. Changes with a small blast radius on less sensitive code, and there’s usually a lot of that, can get a lighter human pass once that first pass comes back clean. Core and sensitive paths still need an owner and a careful human review, and that’s where I spend my attention. Either way, a person approves the merge. Agents do the first pass and humans cover blast radius. Nobody in that loop presses enter for thirteen hours, because pressing enter was never the human’s job. The job is deciding what deserves attention. The “no sense of victory” in that post is what it feels like when a company takes that decision away from you too.
If you’re the one pressing enter
Most advice about this is written for people who get to set policy. A lot of the people in that Reddit thread don’t. So here’s what I’d do if I were two weeks into that job.
Truly understand what you want build. Before an agent touches anything, write down what you’re building, what it must not break and how you’ll know it worked. It doesn’t need to be long. That’s where your judgment goes now, and it’s the part of the work you can point to later. Several people in the thread said a version of this: the ones who still felt good about their work had designed the thing and let the agent build it. If you want the sense of victory back, it lives in the decisions.
Use “can I explain this?” as your test. One design lead in the thread asks their team whether they know “every hair on the dog” before they call work their own. I’d apply the same test to code. You don’t need to have read every line, but you should be able to explain what the change does, what it touches and why it’s safe to ship. You can only really be accountable for what you can explain.
Be honest about what you didn’t review. If you weren’t given time to understand a change, say so where people will see it, like the PR description: “agent-reviewed, tests pass, I haven’t read the migration logic.” That isn’t being difficult. It’s what keeps you out of the crumple zone I get to at the end of this post. A team that hides how little it read can’t fix that.
Keep your hands in. Anthropic’s researchers describe a “paradox of supervision”: supervising Claude well takes the very coding skills that fade if you never use them. Some engineers there deliberately solve problems without Claude now and then, even when they know it could handle it. One said it “helps me keep myself sharp.” That’s worth copying, especially early in a career.
If you set the pace
The best counter-argument comes from startups where all the documents and code are AI-made: “they work for us , we dont work for them. Every single thing has a responsible person who needs to be able to explain what we have done.” If you’re the person setting expectations, here’s what I think follows from it.
Accountability needs authority. If an engineer will be blamed when a change fails, they need a say in how fast changes go out and how much they get to understand first. Holding someone responsible for a pace they didn’t set, on code they weren’t given time to understand, is exactly what the thread calls being a “meat proxy.” It isn’t fair, and it doesn’t work as a control either.
Measure what shipped, not how much. Merged PRs and lines of code are easy to count, and they’re the numbers that turned pressing enter into the whole job. Even Anthropic’s own write-up on its 8x output number calls lines of code “an imperfect measure.” Watch incidents, rollbacks, time to recover and what customers actually experience.
Budget for understanding like any other capacity. One commenter put the new constraint plainly: “Writing code isn’t bottleneck, but reading and evaluating it is.” Anthropic has said much the same about review. The answer isn’t to read nothing. It’s to decide, area by area, how much human attention a change needs, and plan the work around that. Automated review helps a lot here, but Anthropic’s stated goal for it is to close the gap “so reviewers can actually cover what’s shipping,” not to take reviewers out of the loop.
Make room for mentoring on purpose. Juniors used to learn by asking seniors questions and reading their review comments. If Claude answers the questions now, you have to create the rest deliberately: pairing on plans, having juniors explain agent-written changes back to someone, leaving some work manual. “What juniors?” was one of the bleaker replies in that thread. It shouldn’t be the answer at your company.
Keep what you ask people to sign human-sized. This applies to documents as much as code. One commenter’s product team had AI read the legacy codebases and produce a feature-and-gap report: an HTML file over 100 pages long and a spreadsheet with 30 tabs of hundreds of rows each. When they pushed back that it wasn’t fit for human consumption and asked to start with the high-level gaps, they were treated like they weren’t a team player. A 100-page generated report nobody can read has the same problem as a 5,000-line diff nobody read. Agents make long documents free to produce. A person still has to be able to judge them, and asking for the one-page version isn’t obstruction. It’s review.
“But our competitors don’t read the code”
The most reasonable pushback I’ve seen came from another startup engineer. Their management doesn’t even like shipping without reading. They just feel they have no choice, because the next company does it and they can’t compete on price otherwise. I take that seriously.
My answer is the second cost. Skipping the checks doesn’t make failures free. It moves their cost later, when it’s bigger and lands on your customers.
So I don’t think the competitive question is reading versus not reading. It’s which team can build cheap checks that actually work, and point its people’s limited attention at the changes that can really hurt. The team that wins isn’t the one that reads nothing. It’s the one that knows what’s worth reading.
So who writes the tests?
One reply to Thorsten’s list asked the question I’d been circling. A unit test captures what you know about how a system should behave and checks it against something you don’t fully trust, which is your own future work. “If the thing you don’t trust is also writing the tests what is it accomplishing?”
It’s a fair question. In Anthropic’s research on reward hacking, models learned to call sys.exit(0) so the test harness would exit before any assertion could fail. A test written or controlled by the thing it’s testing doesn’t prove much.
The way out is to ask where a test gets its authority. Aviation’s answer is independence. DO-178C, the standard for airborne software, requires the most critical verification to be done by someone other than the author, and a qualified tool can count as that someone. Having one Claude write the tests and another write the code catches the crudest failures, but a second copy of the same model shares the first one’s blind spots. Real independence comes from a different source of truth: a spec a person wrote, a reference implementation, a proof.
The best example I know is Nicholas Carlini’s C compiler. Sixteen Claude agents, nearly 2,000 sessions and just under $20,000 produced a 100,000-line compiler in Rust that can build a bootable Linux. His main lesson was about the checker rather than the agents: “the task verifier is nearly perfect, otherwise Claude will solve the wrong problem.” When the agents got stuck on the kernel, he used GCC as a known-good reference to corner each bug.
SQLite shows where this leads. The library is about 156,000 lines of C, and its test code is 590 times larger. Its most thorough test suite reaches 100% branch coverage, was designed to meet an avionics testing standard, and is proprietary. SQLite gives away the code and licenses the tests. So here’s how I’d rephrase Thorsten’s point. Unit tests as notes from you to your future self will matter less, because your future self won’t be the one changing the code. Tests as an independent check on an author you don’t fully trust will be the most valuable code you own.
The expensive bugs were always upstream
Thorsten says most bugs will come from asking for the wrong thing.
Ariane 5 was destroyed less than a minute into its first flight because navigation code reused from Ariane 4 overflowed on a trajectory Ariane 4 never flew. The inquiry board found that the specification didn’t include the new trajectory. Mars Climate Orbiter was lost because one team’s software produced pound-force seconds where the interface expected newton-seconds.
Each failure lived at a join: between a requirement and the real flight, between two teams’ units, between a deployment and eight servers. That’s where the expensive bugs live, and it’s where models are weakest today. Anthropic’s own assessment is that Claude can match skilled researchers at running a well-specified experiment, but that “large performance gaps persist when it comes to Claude exercising judgement in choosing goals.”
I’ve written about the 70% problem and later the 80% problem. Each time the number went up, what was left for the human was less typing and more judgment. That’s how I read Thorsten’s claim that the product, design and engineering trio will disappear. The handoffs between three roles go away. The three judgments stay, whoever ends up making them: is this worth building, does it work for the person using it, and will it hold up. He’s also right about one role in particular. The person who takes a ticket, hands it to an agent and reports back without adding any judgment of their own: that job is going away.
The industries that say “never”
The usual pushback is that none of this applies where a bug can cause major problems or lose someone’s money. Today those industries do read the code, and I think they’ll keep doing it longer than optimists expect. But what they actually require is a reason to trust the code, and they’ve accepted machine-generated code before when they had one.
You can qualify a code generator because it gives the same output for the same input. A language model doesn’t. So for now, the practical way to use a model on flight software is the old way: a person reads what it wrote. The way forward is on the checking side, with formal proofs, qualified static analysis and independent test oracles, treating the model as an untrusted author whose every output gets verified.
Finance is closer than people think. A lot of what its rules call review is really about accountability. The standards mostly require that changes be authorized, tested and approved by someone independent, not that a peer reads every line. None of that stops an agent from doing the implementation. It keeps a person accountable for the approval, which is where a person belongs.
Count the nines
The strongest objection I know on timelines comes from Andrej Karpathy, who said last year that this is “more accurately described as the decade of agents.” His argument comes from self-driving, where “every single nine is a constant amount of work.” Getting from 90% reliable to 99% costs as much as getting to 90% in the first place. Waymo started in 2009 and is now on its 15th city.
He’s right that nines are expensive. Where software differs from driving is that a lot of software can buy its nines from the system around the model instead of from the model. A web app can ship behind a flag, watch its error rate and roll back in minutes. A car can’t roll back a collision. So I think timelines split along the second of my two costs: how cheaply you can catch and undo a failure after it ships.
Here are my guesses, specific enough that you can hold me to them:
Consumer software, internal tools and most SaaS: a person reading every line of a routine change will be unusual within two years, though a person will still approve it and own it. Plenty of teams are already there.
Enterprise and financial software: agents will write most of the code on the same timeline, with human approval kept as a control. Over three to five years, that approval shifts from the diff to the evidence.
Flight controls and the highest-risk medical devices: people will keep reading line by line. I don’t expect a regulator to accept safety-critical code on qualified checking alone for many years.
It’s also worth remembering where the loudest version of this conversation happens. In the biggest bubbles, Twitter, we’re ahead of the curve. It’s going to take a long time for the rest of the industry, and the rest of the world, to catch up. But the direction is clear to me.
What happens to the code
Thorsten says there’s no proof that “good code” will matter, since most of what we mean by it is about making code easy for people to work with. I agree for the parts that were purely about human comfort, like formatting. But some properties matter more to an agent than they ever did to us: names unique enough to grep, modules small enough to fit in a context window, tests that fail clearly, clear boundaries between parts. Without those, an agent will still make the change. It just can’t see what else the change affects. Good code, now, is code an agent can change without breaking something it can’t see.
I’ve been involved in open source for a long time, and I think it evolves here rather than dies. It’s easier than ever to take a project, make your own copy and reshape it quickly without first understanding all of the code. I wouldn’t be surprised if we increasingly share prompts, or share finished artifacts that people hand to their agents when they want to customize them.
What open source is short on is maintainer attention, and AI both floods it and multiplies it. In January, Daniel Stenberg ended curl’s bug bounty, citing what he called “an explosion in AI slop reports.” Three months later, the rate of real vulnerabilities was back to normal, at double the old report volume. Within a year, the junk problem had turned into a volume problem. What’s most worth sharing shifts toward things that are expensive to produce and cheap to check against: test suites, specs, the record of what broke.
The crumple zone
Madeleine Clare Elish has a name for what happens to people at the edge of automated systems: the moral crumple zone. In a car, the crumple zone is built to absorb the impact so the passengers don’t have to. In a system where automation does most of the work, the nearest human often plays the same role. They take the blame for a failure they had little real power to prevent.
The engineer pressing enter for thirteen hours is standing in one. Their name is on the approval. But the pace, the checks and the decision about what was worth reading were all made somewhere else. When something breaks, the incident review will find the human who approved it.
Reading every line was never what made software trustworthy. It was one way to make sure a person understood what they were shipping and was in a position to say no. The line-by-line read is going away for most code, and I think that’s fine. The understanding and the ability to say no can’t go with it.
So here’s the advice I’d give now, in place of what I said two years ago. Know what’s worth reading. On the code you don’t read, build checks you’d actually trust, and keep them independent of whatever wrote the code. Write down what you’re building before an agent builds it. Be able to explain everything you ship, and be honest about what you can’t explain. If you set the pace for other people, give them authority that matches the accountability you’re asking of them.
I once called good code a love letter to the next developer. I still believe that. More and more, though, the next developer is an agent, so the letter looks different now. It’s code the agent can change without breaking something it can’t see. The craft didn’t disappear. It moved to the parts that decide whether the code deserves to be trusted.
Thanks to the newsletter’s sponsors for their support over the last few months. As I’ve joined a new role full-time, I’ve put a pause on sponsors for future issues. Opinions here expressed are my own and do not express the views or opinions of my employer. I hope to continue writing and sharing my thoughts on the newsletter as long as they’re helpful to you :)
The bedrock of these models is comprised of OUR knowledge and expertise. So, what works well for us, works well for them, as well.
Thus, much of our best practices around coding yield the same benefits to an agent as they do to a human. It's in our best interest for the managers of these agents to maintain that same dedication to high quality, maintainable, readable code...because it will yield better results for us downstream.
The "who writes the tests" part hit close to home. I recently ran a plan through my own agent setup where each phase was done by one agent and reviewed by a separate one that only saw the diff and the acceptance criteria, not the executor's reasoning. Out of five phases the executors had already marked as done, three had serious problems, and all their tests were green. The bugs sat exactly in what those tests didn't check, because the same agent wrote both the code and the tests.
One of them was a small cousin of the sys.exit(0) story: in a task set for comparing models, a task could be passed by just committing something and saying it's already done. What helped was checking the checks. Now every task has a known correct solution that must pass, a stub that does nothing and must fail, and a few deliberately tricky variants.
The most useful review question turned out to be not "does this work?" but "how could a wrong solution get through?". I wrote up the whole run here if anyone's curious: https://swarmery.substack.com/p/why-i-dont-believe-an-agent-when